Run Referral Automation in Parallel Without Creating Duplicate Work
Plan a referral automation parallel run with explicit action authority, linked evaluation records, discrepancy evidence and safe staff takeover boundaries.
This is a proposed administrative evaluation method. It does not prescribe clinical decisions, payer rules or a universal trial duration.
Why parallel runs create duplicate work
Health IT changes both clinical and administrative workflow, which is why AHRQ's workflow assessment toolkit frames implementation as a workflow question rather than a software question (AHRQ Workflow Assessment for Health IT Toolkit). A parallel run adds another process to the same workflow. Its scope needs to specify which process can execute each action.
Consider this synthetic failure scenario. A referral coordinator sees an automated status of "sent to specialist" but is not sure whether the fax went, so she sends it again. The specialist office receives two faxes and calls to ask which one is current. The patient gets two scheduling calls. The run then produces a discrepancy that was caused by the run itself, not by either system.
The charter should pair a written ownership rule with controls the team can demonstrate.
Step 1: Choose shadow observation or controlled parallel operation
Two useful designs answer different questions. Define the mode for each action and make transitions explicit.
Shadow observation: automation reads approved inputs and records what it would propose in a separate evaluation space. Staff retain execution authority. Verify that the shadow configuration cannot send messages, create production work items or update the EHR. This can compare interpretations and proposed actions; it does not establish reliable live execution or recovery.
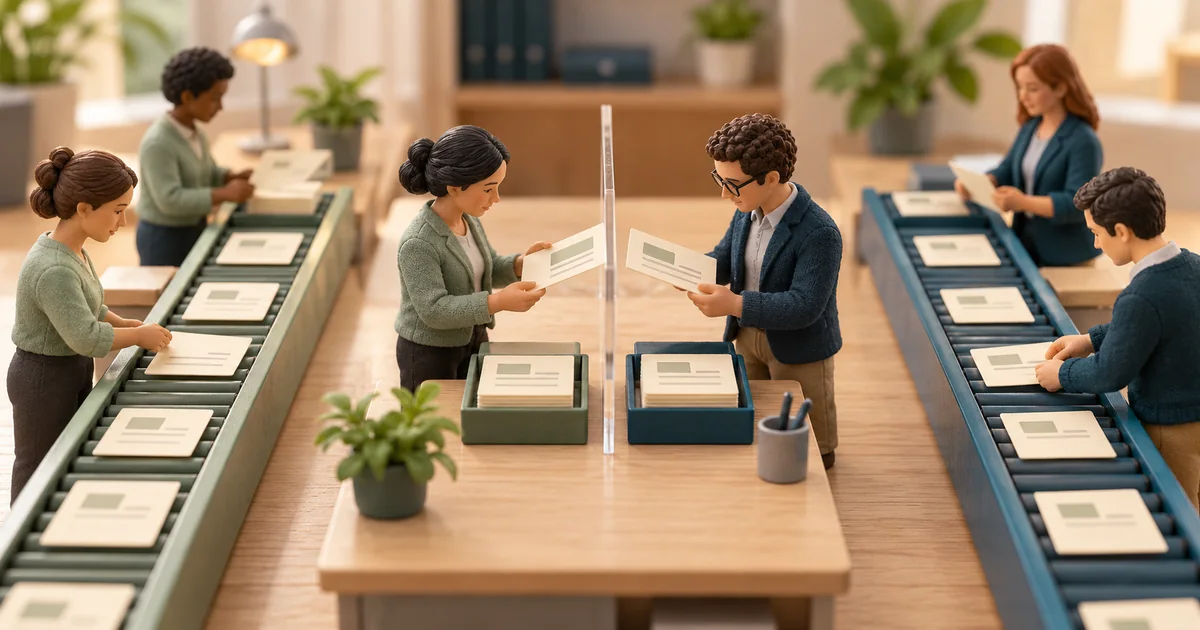
Controlled parallel operation: automation owns a bounded set of approved actions while staff retain the others. A person may observe and verify an automated action without repeating it. Any transfer of execution authority must include pending work, queued retries and the last confirmed result.
The Operational AI Evaluation Kit recommends inspecting normal work, missing data and exceptions. Apply that approach in an agreed test environment before a live trial. A clean shadow comparison alone is not sufficient evidence for production writes, contact permissions or failed-action recovery.
Step 2: Give one system authority for every real action
Create a charter with scope, mode, run owner, dates, covered actions and pause authority. Complete this matrix for the proposed run. Its blank cells are decisions to make, not assumed assignments.
| Action | Authorized execution path | Observer may do | Result and takeover evidence |
|---|---|---|---|
| Log the referral | Decide: one system | Compare with evaluation record | Existing referral identifier |
| Extract administrative fields | Decide: one system | Flag disagreement without writing | Source-to-field comparison |
| Attach documents | Decide: one system | Inspect intended record and version | Correct document identity, not count alone |
| Contact the patient | Decide: one system | Review proposed content | Contact state and confirmed send result |
| Send the packet | Decide: one system | Inspect prepared packet | Destination and transmission evidence |
| Update EHR status | Decide: one system | Compare proposed meaning | Actual field change and history |
| Complete the administrative task | Decide: one system | Inspect endpoint evidence | Agreed endpoint and remaining work |
Verify that observer actions do not trigger sends, writes or duplicate staff tasks. Ask how permissions, queue assignment or another demonstrated control enforce the chosen execution path. A written "one owner" rule does not by itself prevent two systems from acting simultaneously.
Before a staff takeover, inspect whether the automated action completed, failed or has an unknown result. Stop or account for pending retries before repeating it. Do not automatically fall back to manual execution when a send is uncertain, since it may already have occurred. Assign uncertain actions to the run owner under the agreed recovery process.
Specify which actions can be paused or corrected and which effects need reconciliation. Do not assume every message or record change can be reversed.
Step 3: Build paired records and a discrepancy log
Every referral in scope gets an evaluation reference linking the existing production referral to the observation or proposal. Keep the comparison record separate from production work. At the charter-defined cadence, reconcile the references and log disagreements.
Discrepancy log fields
- Pair ID and referral type
- Field or action in disagreement
- Manual value and automation value
- Which was correct, if determinable, and how you know
- Root cause category: source document, data entry, mapping, timing, out of scope, unknown
- Owner and resolution date
- Whether a duplicate outbound action occurred
A duplicate outbound action is a finding to investigate under the charter. Zero duplicates in a properly restricted shadow run mainly confirms that the no-action boundary held during observation. It does not prove that a future live execution path handles retries or competing staff actions correctly.
Synthetic example
Suppose a shadow run links 240 existing referrals to 240 evaluation records. It records 31 discrepancies: 14 uncertain document interpretations, 9 mapping disagreements, 5 timing differences after later information arrived and 3 still under investigation. The categories total 31 and are defined as mutually exclusive for this example. They are not measured customer results.
A mid-run mapping change requires a version marker and a new observation segment. These totals alone cannot establish that discrepancies declined after the change. Compare the before-and-after denominators and case mix before drawing even a limited conclusion. Record zero observed outbound duplicates separately from accuracy and execution evidence.
Step 4: Compare staff effort, outcomes and unresolved exceptions
Keep three comparisons separate and do not combine them into one score.
Staff effort. Record minutes per referral for the manual path and for verification work in the parallel path. Separate ordinary processing, trial-only verification, correction and setup time. A shadow run does not show realized labor savings because staff still perform the underlying work. Any future-capacity estimate needs explicit assumptions about the work retained after the trial.
Outcome status. Define completion in observable terms before the run, including the final status and where it is recorded, which the evaluation kit treats as a core evidence check (Operational AI Evaluation Kit). For bounded execution, count the actions that reached the agreed endpoint with raw counts and denominators. In shadow mode, compare the proposal with the observed staff result; do not report the proposal as automated completion.
Unresolved exceptions. List every open item at run end with an owner. An exception queue without ownership is a red flag in any evaluation, and it is a worse one in a parallel run because the open item may be sitting in two queues.
If you want a structured way to score the evidence the run produced, the Operational AI Evaluation Kit uses a 0 to 3 scale from not addressed to verified and treats privacy, security, safety, authorization and accountability issues as gates that a high total cannot offset. Use the same gate logic here: a clean discrepancy log does not excuse an unclear write authority.
Step 5: Use explicit exit criteria to stop, extend or expand
Agree decisions before the run, using the workflow's own requirements:
- Pause affected actions when authority is unclear, a duplicate action is observed or the action result cannot be established. Assign investigation and reconcile any effects before resuming under the approved plan.
- Extend evidence gathering when planned exception cases did not occur or a changed rule needs a new observation segment. Do not extend simply to wait for a favorable number.
- Expand the bounded scope only after the next action's execution, correction, staff takeover and pending-retry behavior are demonstrated and accepted. Document any unresolved requirement that prevents expansion.
Do not treat known discrepancy causes or named owners as proof that an unresolved problem is acceptable. Make that decision explicitly. Update the authority matrix and reconcile in-flight work when the scope changes.
The implementation guide covers broader rollout planning, and the adoption guide covers ongoing staff use. To inspect a proposed action boundary, book a demo with the charter and a synthetic takeover scenario.
How this fits a referral coordination decision
A parallel run is evidence gathering, not procurement. It tells you how a specific automation behaves on your referrals, with your documents and your exceptions. Linear Health describes its referral coordination software as operational AI that keeps the team in the loop on the portion of work that is not automated, which is a vendor description rather than a measured result, and the authority matrix is one way to make that loop explicit during evaluation (referral coordination software).
When the run ends and you are deciding which rows move to automation next, a working session against your own discrepancy log is more useful than a general walkthrough. Book a demo with that log in hand if you want the discussion grounded in your data.
Frequently asked questions
How long should a parallel run last?
Can staff and automation work on the same referral?
Should we create a second referral to compare results?
Does a shadow run prove execution is reliable?
What if an automated send has an unknown result?
Sources
Sources accessed November 9, 2026.
Linear Health publishes educational articles about operational AI for healthcare.